The video below will provide an example of using random forest to detect fraud with python.

The video below will provide an example of using random forest to detect fraud with python.

In this post, we will learn how to detect fraud when our data is not labeled with ground truths for testing purposes. Previously, we determined the number of clusters that are appropriate for our data. Now, we will take this knowledge and identify potential examples of fraud.
Libraries
We will start with the necessary libraries and the loading of our data.
from sklearn.cluster import KMeans
from scipy.spatial.distance import cdist
from sklearn.model_selection import train_test_split
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
from sklearn.metrics import confusion_matrix, classification_report, roc_auc_score
from sklearn.preprocessing import MinMaxScaler
df = pd.read_csv("C:/Users/dthom/Documents/python/fraud/chapter_3/chapter_3/banksim_adj.csv")
The KMeans algorithm will be used to label our data as belonging to specific clusters. The cdist() function will be used to calculate the distance between individual data points and the cluster centroids. The train_test_split() function will be used to divide our data into training and testing sets. pandas and numpy will be used for data cleaning. matplotlib will be use to create a visualization. The confusion_matrix(), classification_report, and roc_auc_score functions will be used for model assessment. Lastly, the MinMaxScaler() function will be used to scale the data.
Data Preparation
In the code below, we scale the X values and create our training and testing sets. Notice how we leave out column 3 in the X values, as this column is our y values. The y values are actually the labels of fraud. What we are doing here is assuming we don’t have the values. We will then compare what we find in our analysis using Kmeans to the y values.
X = df.iloc[:, [1, 2] + list(range(4, 19))]
y = df.iloc[:, 3]

# Take the float values of df for X
X = df.values.astype(float)

# Define the scaler and apply to the data
scaler = MinMaxScaler()
X_scaled = scaler.fit_transform(X)

# Split the data into training and test set
X_train, X_test, y_train, y_test = train_test_split(X_scaled, y, test_size=0.3, random_state=0)
We are not scaling our y values because they are not used in creating our clusters.
Model Development
We will now create our clusters. We already know that using three clusters is appropriate, so we use the KMeans() function to set this value along with the seed number of 42. We then take this information and predict cluster values for the test data. Last, we put the cluster centers into their own object and display the values to show what is happening with the data.
# Define K-means model
kmeans = KMeans(n_clusters=3, random_state=42).fit(X_train)

# Obtain predictions
X_test_clusters = kmeans.predict(X_test)
X_test_clusters_centers = kmeans.cluster_centers_
print(X_test_clusters_centers)

[[ 4.86803753e-01  4.94050179e-01  1.11442274e-01  1.49186219e-16
   1.60982339e-15 -6.93889390e-18  1.73472348e-18 -6.59194921e-17
   4.85722573e-17  1.73472348e-16 -1.86482774e-17  7.80625564e-18
  -2.60208521e-17 -2.81892565e-18 -1.40946282e-18  4.85722573e-17
   2.42861287e-17  1.00000000e+00  1.21430643e-17]
 [ 4.86841962e-01  5.03923667e-01  1.12597701e-01  8.32667268e-17
   1.00000000e+00  2.25514052e-17 -3.46944695e-18 -2.77555756e-17
   1.17961196e-16  1.31838984e-16 -1.04083409e-17  1.21430643e-17
   1.04083409e-17 -2.38524478e-18 -1.19262239e-18  3.98986399e-17
   1.99493200e-17  1.00000000e+00  9.97465999e-18]
 [ 5.69661624e-01  4.93834527e-01  3.60411064e-01  1.69451074e-01
   4.03341289e-01  7.51789976e-02  1.43198091e-02  7.39856802e-02
   2.39856802e-01  1.96897375e-01  2.26730310e-02  2.62529833e-02
   6.32458234e-02  9.54653938e-03  4.77326969e-03  6.68257757e-02
   3.34128878e-02  1.66533454e-15  1.67064439e-02]]
We will now calculate the distance each data point is from its assigned cluster. The np.linalg.norm() function computes the norm (magnitude) of a vector or matrix in NumPy, and we do this for every data point.
#calculate distance from cluster centroid
dist = [np.linalg.norm(x-y) for x, y in zip(X_test, X_test_clusters_centers[X_test_clusters])]
print(dist)

[0.3010076776055849, 1.124798110868828, 0.6818089230629063, 0.7301151147782995, 1.0838984579838724, 0.20656858215304805, 0.4606011452724887, 0.09018296562281172, 0.4918133960385591]
Now that we know the distances, we look for extreme values from the centroids. We convert our dists into percentiles and calculate the values that are in the 95th percentile or higher
# Create fraud predictions based on outliers on clusters
km_y_pred = np.array(dist)
km_y_pred[dist >= np.percentile(dist, 95)] = 1
km_y_pred[dist < np.percentile(dist, 95)] = 0
Values that are in the 95th percentile or above are labeled as 1, while all other values are labeled as 0. The values labelled as 1 could potentially be instances of fraud. In a real situation with unlabeled data, this is where your analysis would end, and you would turn the results over to a subject expert who would determine which examples are fraudulent.
Model Assessment
Now we will see how well our model performs under the assumption of the data points we identified as fraudulent. The confusion matrix and ROC Score are below.
# Create a confusion matrix
km_cm = confusion_matrix(y_test, km_y_pred)

# Obtain the ROC score
print("ROC Score {}"  .format(roc_auc_score(y_test, km_y_pred)))
print(classification_report(y_test, km_y_pred)) # false positives!

Roc Score 0.9703717698082832
              precision    recall  f1-score   support

           0       1.00      0.98      0.99      2099
           1       0.52      0.97      0.67        58

    accuracy                           0.97      2157
   macro avg       0.76      0.97      0.83      2157
weighted avg       0.99      0.97      0.98      2157
The results indicate a strong model overall, as the ROC Score is close to 1 (0.97), but the model struggles with false positives. We know this from the precision being 0.52. In the code below, we create a visual of the confusion matrix
# Plot the confusion matrix in a figure to visualize results
km_cm= confusion_matrix(y_test, km_y_pred)
from matplotlib.colors import ListedColormap
import seaborn as sns
ax= plt.subplots(figsize=(5,5))
sns.set(font_scale=1.4)
with sns.axes_style('white'):
    sns.heatmap(km_cm, cbar=False, square=True,annot=True,fmt='g',
cmap=ListedColormap(['gray']),linewidths=2.5)
plt.show()
You can see the false positives in the upper right-hand corner. The context determines if this is a problem.
Conclusion
The example above illustrates one method for identifying fraudulent examples in a dataset. This was a multi-step process that involved creating clusters and determining which examples were considered outliers in comparison to the cluster centroids.

This post demonstrates the use of Random Forest for fraud detection in Python. Random Forest involves building not just a single decision tree, but an ensemble of trees, which enhances the model’s predictive accuracy. Below are the libraries required to begin data preparation.
Libraries
We need pandas for loading our data, and we need numpy to convert our data to an array. Below is the code to load our data and convert it to an array.
import pandas as pd
import numpy as np
Data Prep
Below is the code for loading the data and converting it into an array. The exact location of the data is not shown inside the pd.read_csv function. We need to create two arrays. One array will contain the X values, and the other array will contain the y values. The X values will be columns 2 to 29, and the y value is column 30.
df = pd.read_csv(data_loc)
X = df.iloc[:, 1:30]
X = np.array(X).astype('float')
y = df.iloc[:, 30]
y=np.array(y).astype('float')
Next, we will look at the shape of the data and the percentage of positive and negative instances of fraud.
Data Exploration
In the code below, we will determine the number of examples in this dataset. To do this, we use the len() function as shown below.
# Count the total number of observations from the length of y
total_obs = len(y)
total_obs
7300
In all, we have 7300 rows of data. In the code below, we will determine the percentage of the data that is an instance of fraud and what is not.
# Count the total number of non-fraudulent observations
non_fraud = [i for i in y if i == 0]
count_non_fraud = non_fraud.count(0)

# Calculate the percentage of non fraud observations in the dataset
percentage = (float(count_non_fraud)/float(total_obs)) * 100
# Print the percentage: this is our "natural accuracy" by doing nothing

print(percentage)
95.8904109589041
We begin by counting non-fraud cases. This is done by creating a for loop that counts each instance in y where the value is 0. These instances are then totaled and stored in an object called count_non_fraud.
Next, we calculate the percentage by dividing count_non_fraud by the total number of observations. The result is saved in an object called percentage. Finally, we print the results.
Model Development
We will now develop our model. Doing this will require us to load additional libraries as shown below
# Import the random forest model from sklearn
from sklearn.ensemble import RandomForestClassifier
from sklearn.model_selection import train_test_split
from sklearn.metrics import confusion_matrix
from sklearn.metrics import classification_report
The RandomForestClassifier is the algorithm we will train and use. train_test_split will split our data into train and test sets. Lastly, confusion_matrix and classification_report will be used to assess the quality of our. model
Our next step will be to separate our data into a train and test set. The code for this is below
# Split your data into training and test set
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=.3, random_state=0)
We create four objects on the left-hand side of the equal sign. On the right-hand side of the equal sign, we are using the train_test_split() function to create our objects. Inside the function, we have our X and y objects, which we created earlier. There are also two arguments inside the function. test_size indicates the size of the test sets, which in our case is 30% of the data. random_state is how we set the seed for reproducibility. We are creating train and test sets so we can use our train model on unused data, which is standard practice.
In the code below, we will create an instance of our algorithm and train our model.
# Define the model as the random forest
model = RandomForestClassifier(random_state=5)

# Fit the model to our training set
model.fit(X_train, y_train)
Now we will take our trained model and predict with our test set.
# Obtain predictions from the test data
predicted = model.predict(X_test)
We don’t know how well our model has done yet. We will find this out by assessing the model in the next section.
Model Assessment
In the code below, we use the classification_report() and confusion_matrix() functions. The classification_report() function shares various performance metrics that we can use to assess our model. The confusion_matrix() function provides a table of all the true and false positives and negatives. Below is the code
# Print the accuracy performance metric
print('Classifcation report:\n', classification_report(y_test, predicted))
conf_mat = confusion_matrix(y_true=y_test, y_pred=predicted)
print('Confusion matrix:\n', conf_mat)

Classifcation report:
               precision    recall  f1-score   support

         0.0       0.99      1.00      1.00      2099
         1.0       0.99      0.80      0.88        91

    accuracy                           0.99      2190
   macro avg       0.99      0.90      0.94      2190
weighted avg       0.99      0.99      0.99      2190

Confusion matrix:
 [[2098    1]
 [  18   73]]
The results indicate high accuracy (99%), which is expected in a fraud detection situation. Precision is also high (99%), indicating that the model is effective at avoiding false negatives. However, recall is only 80% which implies the model struggles with avoiding false positives. The F1-score is an aggregate measure of precision and recall.
Conclusion
Random Forest is yet another method for detecting fraud. The power of this algorithm lies in its ability to robustly predict which examples are fraudulent through the development of multiple trees for prediction.

It is common for data to come without being labeled with examples of fraud. In such situations, the analyst will identify potential instances of fraud. In this post, we will learn how to overcome this problem using unsupervised learning.
The main strategy for addressing unlabeled data is to cluster the data using kmeans or another clustering algorithm. Once the clusters are developed, you will then find outliers that do not fit inside any of the clusters. Even at this point, you have suspected instances of fraud, and it is now necessary to have an expert examine the individual cases
Load Libraries
We begin by loading the needed libraries and looking at them
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
# Import the scaler
from sklearn.preprocessing import MinMaxScaler
df = pd.read_csv("C:/Users/dthom/Documents/python/fraud/chapter_3/chapter_3/banksim_adj.csv")
Pandas and numpy are needed to manipulate the data. We will use matplotlib to make visuals. The MinMaxScaler will be for scaling the data before creating our clusters. Below is some of the columns from the data.
print(df.head())

   Unnamed: 0  age  amount  fraud  M  es_barsandrestaurants  es_contents  \
0           0    3   49.71      0  0                      0            0
1           1    4   39.29      0  0                      0            0
2           2    3   18.76      0  0                      0            0
3           3    4   13.95      0  1                      0            0
4           4    2   49.87      0  1                      0            0
There are many more columns than this, as this is just a peak.
Scale the Data
As you examine the data, you can see that the scaling differs for each variable. The kmeans algorithm is sensitive to scaling, so we must ensure that the scaling is the same for all variables. In the code below, we convert the data to float values and then scale the data
# Take the float values of df for X
X = df.values.astype(float)

# Define the scaler and apply to the data
scaler = MinMaxScaler()
X_scaled = scaler.fit_transform(X)
Below is what the data looks like now.
X_scaled

array([[0.00000000e+00, 5.00000000e-01, 2.06810025e-01, ...,
        0.00000000e+00, 1.00000000e+00, 0.00000000e+00],
       [1.38908182e-04, 6.66666667e-01, 1.62478579e-01, ...,
        0.00000000e+00, 0.00000000e+00, 0.00000000e+00],
       [2.77816363e-04, 5.00000000e-01, 7.51345685e-02, ...,
        0.00000000e+00, 1.00000000e+00, 0.00000000e+00],
       ...,
       [9.99722184e-01, 1.66666667e-01, 1.00000000e+00, ...,
        0.00000000e+00, 0.00000000e+00, 1.00000000e+00],
       [9.99861092e-01, 1.66666667e-01, 1.00000000e+00, ...,
        0.00000000e+00, 0.00000000e+00, 0.00000000e+00],
       [1.00000000e+00, 6.66666667e-01, 1.00000000e+00, ...,
        0.00000000e+00, 0.00000000e+00, 0.00000000e+00]])
The data looks much different, but the columns are still present. The main differences are that the values are scaled appropriately so that no variable has too much influence compared to the others.
Determine Number of Clusters
The next step is to determine the number of clusters. We will need the KMeans algorithm and the cdist() function to obtain the values for the elbow plot. Since we don’t know how many clusters we will set K for, anywhere from 1 to 10 clusters
# Import MiniBatchKmeans
from sklearn.cluster import KMeans
from scipy.spatial.distance import cdist
# Define the model

distortions = []
K = range(1,10)
for k in K:
    kmeanModel = KMeans(n_clusters=k).fit(df)
    distortions.append(sum(np.min(cdist(df, kmeanModel.cluster_centers_, 'euclidean'), axis=1)) / df.shape[0])


plt.plot(K, distortions, 'bx-')
plt.xlabel('k')
plt.ylabel('Distortion')
plt.title('The Elbow Method showing the optimal k')
plt.show()
in the code above, we create a for loop to calculate the number of clusters from 1 to 10. For each of these clustering combinations, we calculate the Euclidean distance for each centroid. We then plot this in the plot below. We are looking for the elbow in the plot at which the reduction in distortion drops significantly, which indicates that adding more clusters is no longer beneficial.

In the plot above, the elbow appears at k = 3. This indicates that we need 3 clusters for a fraud analysis.
KMeans and Groups
We can now explore our data by first fitting our 3 clusters to our data and creating a column called ‘predict’. With this new column, we can calculate group means and understand the characteristics of each group.
km=KMeans(3,init='k-means++',random_state=3425)
km.fit(df.values)

df['predict']=km.predict(df.values)
print(df.groupby('predict').amount.mean())
print(df.groupby('predict').age.mean())
print(df.groupby('predict').es_travel.mean())

predict
0    45.853826
1    32.604894
2    32.477959
Name: amount, dtype: float64
predict
0    2.982471
1    3.007503
2    2.979114
Name: age, dtype: float64
predict
0    0.007513
1    0.000000
2    0.000000
Name: es_travel, dtype: float64
The values for the amount spent are higher for group 0 compared to groups 1 and 2. The ages of each group are about the same as are the values for es_travel. This is a cursory analysis, and many more values and even visualizations could be developed.
Plot of Groups
In the example below, we examine the age, amount, and cluster simultaneously. The goal here is to see if any patterns emerge.
clust_map={0:'group 1',1:'group 2',2:'group 3'}
df['perf']=df.predict.map(clust_map)
d_color={'group 1':'y','group 2':'r','group 3':'g'}

fig, ax=plt.subplots()
for clust in clust_map.values():
        colored=d_color[clust]
        df[df.perf==clust].plot(kind='scatter',x='amount',y='age',label=clust, ax=ax, color=colored)
plt.show()
In the code, we assign each cluster a name (i.e., “group 1”) and a color (i.e., “yellow”). We then create a for loop that plots all the values on a scatterplot as shown below.

It appears that group 3 has the bulk of the lower valued amounts. Group 2 has a lot of mid-level amounts with some extreme values, while group 1 has a large number of extreme values.
Conclusion
The next step in this process is to determine which examples do not fit within any of these three clusters. The outliers could be examples of fraud.

In this post, we will learn how to do exploratory work to determine where fraud is in a dataset. Such knowledge can be used to inform the development of a model.
Libraries
Below are the libraries we are using. The setup is simple.
import pandas as pd
import matplotlib.pyplot as plt
No data preparation is required in this analysis. Therefore, we will proceed to the exploratory process. What we will do is examine the data and drop the useless variable, as shown below.
df=df.drop('Unnamed: 0', axis=1)
print(df.head())

  age gender           category  amount  fraud
0   3      F  es_transportation   49.71      0
1   4      F          es_health   39.29      0
2   3      F  es_transportation   18.76      0
3   4      M  es_transportation   13.95      0
4   2      M  es_transportation   49.87      0
We will now examine fraud by groups
Find Fraud by Groups
We will start by filtering for only data that is considered fraud.
# Create two dataframes with fraud and non-fraud data
df_fraud = df.loc[df.fraud == 1]
df_non_fraud = df.loc[df.fraud == 0]
We will be pulling from the df_fraud dataset and the df dataset for the rest of this post. We will group our data according to category, age, and gender.
The code finding fraud by group is complicated, but here is what we are doing.

Below is the code and output
#Fraud by category
category_fraud=df_fraud.groupby('category').sum('amount').sort_values(['fraud','amount'],ascending=False)

#average amount and percent of fraud to non-fraud
category_fraud[['avg_amount','fraud_per']]=df.groupby('category').mean('fraud')

#average amount of fraud
category_fraud['average_fraud']=category_fraud['amount']/category_fraud['fraud']

#Examples by category
category_fraud['n']=df['category'].value_counts()

#Change column order and sort values
category_fraud=category_fraud.reindex(columns=['n','fraud','fraud_per','average_fraud','amount','avg_amount'])
category_fraud=category_fraud.sort_values(['fraud_per','fraud'],ascending=False)

print(category_fraud)
What we learn from this is the following
We will now repeat this process for age and gender
age_fraud=df_fraud.groupby('age').sum('amount')
age_fraud[['avg_amount','fraud_per']]=df.groupby('age').mean('fraud')
age_fraud['average_fraud']=age_fraud['amount']/age_fraud['fraud']
age_fraud['n']=df['age'].value_counts()
age_fraud=age_fraud.reindex(columns=['n','fraud','fraud_per','average_fraud','amount','avg_amount'])
age_fraud=age_fraud.sort_values(['fraud_per','fraud'],ascending=False)
print(age_fraud)

        n  fraud  fraud_per  average_fraud      amount  avg_amount
age
0      40      2   0.050000     210.473700    420.9474   49.468935
4    1279     46   0.035966     165.624843   7618.7428   36.197985
2    2333     67   0.028718     190.049045  12733.2860   37.228665
1     713     19   0.026648     191.477305   3638.0688   35.622829
5     792     19   0.023990     184.388358   3503.3788   37.547521
3    1718     40   0.023283     210.251670   8410.0668   37.279338
6     314      7   0.022293     186.037086   1302.2596   36.700852
The main points are
Lastly, gender
gender_fraud=df_fraud.groupby('gender').sum('amount')
gender_fraud[['avg_amount','fraud_per']]=df.groupby('gender').mean('fraud')
gender_fraud['average_fraud']=gender_fraud['amount']/gender_fraud['fraud']
gender_fraud['n']=df['gender'].value_counts()
gender_fraud=gender_fraud.reindex(columns=['n','fraud','fraud_per','average_fraud','amount','avg_amount'])
gender_fraud=gender_fraud.sort_values(['fraud_per','fraud'],ascending=False)
print(gender_fraud)

           n  fraud  fraud_per  average_fraud      amount  avg_amount
gender
F       3972    133   0.033484     186.432140  24795.4746   37.842941
M       3212     67   0.020859     191.511576  12831.2756   35.918978
As with age, fraud is an anomaly.
Another point is that the average_fraud is around 180-190 for all groups.
Visual
Below, we will make a histogram comparing the distribution of fraud amounts to non-fraud amounts
# Plot histograms of the amounts in fraud and non-fraud data
plt.hist(df_fraud.amount, alpha=0.5, label='fraud')
plt.hist(df_non_fraud.amount, alpha=0.5, label='nonfraud')
plt.legend()
plt.show()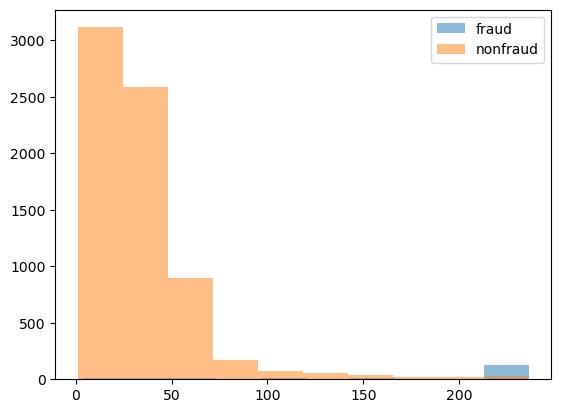
As you can see, the fraud values are a little over 200. This information can be used to set up a model for detecting fraud.
Conclusion
Data exploration is a powerful tool to determine the steps to take in developing your model. These insights help to provide focus in model development and provide you with an understanding of the traits and characteristics of your data. Understanding your data not only helps with model development but also with creating justifications for the approach that is taken.
The video below is a demonstration of how to use logistic regression for fraud detection using Python

In the video below, we will combine the power of SMOTE and logistic regression to develop a model for detecting fraud. SMOTE is used for resampling purposes, while logistic regression is the algorithm we are training.


Ensemble methods enable the use of multiple algorithms to make predictions. Instead of only random forest or logistic regression, you can use both, and the results from each model can be used in a “vote” to make predictions. This is one way to combine the strengths of various models to make stronger predictions
Libraries
Below are the libraries that we are using. We are using three different algorithms for our ensemble (random forest, logistic regression, and decision trees). A new function we are using is the VotingClassifer() function, which is used to create our ensemble model. The other functions have been used and explained previously.
from sklearn.linear_model import LogisticRegression
from sklearn.ensemble import VotingClassifier
from sklearn.ensemble import RandomForestClassifier
from sklearn.tree import DecisionTreeClassifier
from sklearn.model_selection import train_test_split
from sklearn.metrics import confusion_matrix, classification_report, roc_auc_score
from sklearn.model_selection import GridSearchCV
import pandas as pd
import numpy as np
df = pd.read_csv("C:/Users/dthom/Documents/python/fraud/chapter_2/chapter_2/creditcard_sampledata_2.csv")
We will now proceed to the data preparation.
Data Prep
The data preparation is simple. We will separate the independent variables from the dependent variables. The X object represents all of the independent variables, while the y object represents our dependent variable, fraud or no fraud. Once everything is separated, we will create our train and test sets using the train_test_split() function. 70% of our data will be used for training, and 30% will be used for testing.
X = df.iloc[:, 1:30]
X = np.array(X).astype('float')
y = df.iloc[:, 30]
y=np.array(y).astype('float')

# Split your data into training and test set
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=.3, random_state=0)
The next step will involve creating our initial ensemble model.
Model Development
We will use three different classifiers in our ensemble model. The classifiers are logistic regression, random forest, and decision tree. In the code below, each classifier is called, and we also set the various parameters of each classifier to appropriate initial values.
# Define the three classifiers to use in the ensemble
clf1 = LogisticRegression(class_weight={0:1, 1:15},max_iter=1000, random_state=5)
clf2 = RandomForestClassifier(class_weight={0:1, 1:12}, criterion='gini', max_depth=8, max_features='log2',
            min_samples_leaf=10, n_estimators=30, n_jobs=-1, random_state=5)
clf3 = DecisionTreeClassifier(random_state=5, class_weight="balanced")
We will now combine all of our different models into a single model using the VotingClassifier() function. The estimators are given names in quotes, followed by the object after a comma. The “voting” parameter is set to “hard.” Hard voting allows for each model to get one vote per case, with the simple majority winning. For example, if logistic regression and random forest predict fraud simple majority wins this case.
Once we create our combined model, we also fit our data and make predictions. This will allow us to determine the strength of our model.
# Combine the classifiers in the ensemble model
ensemble_model = VotingClassifier(estimators=[('lr', clf1), ('rf', clf2), ('dt', clf3)], voting='hard') #define  voting
ensemble_model.fit(X_train, y_train)
predicted = ensemble_model.predict(X_test) #no probabilities with voting
Next, we will assess the initial results
Model Assessment
In the code below, we use the classification_report() function and confusion_matrix() to see our results.
print(classification_report(y_test, predicted))
print(confusion_matrix(y_test, predicted))

              precision    recall  f1-score   support

         0.0       0.99      1.00      0.99      2099
         1.0       0.89      0.86      0.87        91

    accuracy                           0.99      2190
   macro avg       0.94      0.93      0.93      2190
weighted avg       0.99      0.99      0.99      2190

[[2089   10]
 [  13   78]]
The strength of this model depends on its goals and how it compares to other models. For practice, we will modify the model below.
Model Modification
We will not make any changes to the individual models. Instead, we will make some adjustments to the ensemble model. IN the code below, we are changing the voting to “soft,” which means we are using the probabilities to predict rather than a majority vote. The weights are set so that the second model (random forest) has 4 times the influence compared to the other models. Lastly, the flatten_transform argument is related to the voting argument and changes the output of the data. Below is the code
#Change the weight of the models
# Define the ensemble model
ensemble_model = VotingClassifier(estimators=[('lr', clf1), ('rf', clf2), ('dt', clf3)],
                                 voting='soft',
                                 weights=[1, 4, 1],
                                 flatten_transform=True)
We will now fit our data and predict with it
ensemble_model.fit(X_train, y_train)
predicted = ensemble_model.predict(X_test) #no probabilities with voting
Next, we assess the model
Model Assessment
The model is mostly the same, with a slight improvement in precision. In other words, false positives were reduced.
print(classification_report(y_test, predicted))
print(confusion_matrix(y_test, predicted))

              precision    recall  f1-score   support

         0.0       0.99      1.00      1.00      2099
         1.0       0.94      0.86      0.90        91

    accuracy                           0.99      2190
   macro avg       0.97      0.93      0.95      2190
weighted avg       0.99      0.99      0.99      2190

[[2094    5]
 [  13   78]]
Conclusion
In this post, we saw how models can work together to make stronger, more robust predictions. Ensemble methods are a powerful way to improve fraud detection, and you now know ways to modify the model.
In the video below, we will look at a traditional way to detect fraud using Python. Although this approach is not the most accurate, it is easy to explain and, depending on the context, can provide value.


In this post, we will utilize an algorithm that is slightly more sophisticated than the traditional approach of creating rules. We will use logistic regression to determine whether fraud has occurred or not. The details of how logistic regression works are beyond the scope of this post. However, you can find information on logistic regression here.
Libraries
We will begin by loading our libraries and preparing the data
import pandas as pd
import numpy as np
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import train_test_split
from sklearn.metrics import confusion_matrix
from sklearn.metrics import classification_report

df = pd.read_csv(df_loc)
Pandas and numpy are for data preparation. The rest of the libraries are self-explanatory. LogisticRegression is for logistic regression. train_test_split is for creating our train and test sets. The last two libraries provide tools for assessing our model. The last line of code loads our data. This data is not available on the internet.
Data Preparation
Below, we take a look at the data.
df.head()
Out[5]:
   Unnamed: 0        V1        V2        V3        V4        V5        V6  \
0      258647  1.725265 -1.337256 -1.012687 -0.361656 -1.431611 -1.098681
1       69263  0.683254 -1.681875  0.533349 -0.326064 -1.455603  0.101832
2       96552  1.067973 -0.656667  1.029738  0.253899 -1.172715  0.073232
3      281898  0.119513  0.729275 -1.678879 -1.551408  3.128914  3.210632
4       86917  1.271253  0.275694  0.159568  1.003096 -0.128535 -0.608730
There are more variables than this. Our goal is to predict fraud using the available variables. In the code below, we will separate the X and y values, which will be crucial when creating our training and testing data.
# Separate X, and y values
X = df.iloc[:, 1:30]
X = np.array(X).astype('float')
y = df.iloc[:, 30]
y=np.array(y).astype('float')
In the code above, we instructed Python to use columns 2 to 29 as the X values and convert them into an array. We then instructed Python to extract column 30 and create a separate array.
Create Train and Test Sets
We will now separate our data into training and test sets. We will train the data on the training set and test it with the other set. Below is the code.
# Create the training and testing sets
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=.3, random_state=0)

In the code above, we create four objects, which are all to the left of the equal sign. To the right of the equal sign, we have our function train_test_split(). This function is using our X and y objects from the data preparation section and separating them at a ratio of 70/30. In other words, 70% of the X and y values are for training and 30% are for testing. This is why the test_size argument is set to 0.3. Lastly, the random_state argument determines the seed, allowing you to replicate your approach.
Fit the Model
We will now fit our data to the model. We will create an instance of the logistic regression algorithm and call it “model”. The max_iter argument is to make sure the model converges. Next, we use the .fit() method with our training data. Lastly, we make our predictions using the .predict() method with the testing data
# Fit a logistic regression model to our data
model = LogisticRegression(max_iter=1000)
model.fit(X_train, y_train)

# Obtain model predictions
predicted = model.predict(X_test)
Model Accuracy
The model accuracy is below. The results indicate that the model struggles more with false positives (2) compared to false negatives (1). Whether this is a good model or not depends on comparison to other models and the context of the project.
# Print the classifcation report and confusion matrix
print('Classification report:\n', classification_report(y_test,predicted))
conf_mat = confusion_matrix(y_true=y_test, y_pred=predicted)
print('Confusion matrix:\n', conf_mat)

Classification report:
               precision    recall  f1-score   support

         0.0       1.00      1.00      1.00      1503
         1.0       0.91      0.83      0.87        12

    accuracy                           1.00      1515
   macro avg       0.95      0.92      0.93      1515
weighted avg       1.00      1.00      1.00      1515

Confusion matrix:
 [[1502    1]
 [   2   10]]
Conclusion
Logistic regression is one of many great tools for fraud detection. Compared to other approaches, it is still somewhat simple, which is another major benefit of using it.

In this post, we will modify a model when trying to detect fraud. Most, if not all, machine learning algorithms have parameters that can be adjusted. Adjusting these parameters can potentially improve the accuracy of the model. Each algorithm also has different parameters that can be tuned. For our purposes, we will be using the random forest algorithm.
Libraries
Below are the libraries we will use in this post.
from sklearn.ensemble import RandomForestClassifier
from sklearn.model_selection import train_test_split
from sklearn.metrics import confusion_matrix, classification_report, roc_auc_score
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
The RandomForestClassifier() is the function to create an instance of the random forest algorithm. The train_test_split() function will be used for splitting our data into training and test sets. The confusion_matrix(), classification_report(), and roc_auc_score() functions will be used for assessing our model’s performance. Pandas and numpy are for data preparation. Lastly, matplotlib will be used in conjunction with the roc_auc_score(), which will be explained in detail later.
Data Preparation
Below is the data preparation. In this code, we are separating the independent variables from the dependent variable. Columns 2-29 will be used to predict column 30. Column 30 tells us if the example is fraudulent or not.
X = df.iloc[:, 1:30]
X = np.array(X).astype('float')
y = df.iloc[:, 30]
y=np.array(y).astype('float')
For the X object above, we pull columns 2-29. Then we convert the X object to an array in the next line. We repeat this process for the y object, but we only pull column 30.
In the code below, we are now splitting our X and y objects into training and testing data. The training data teaches the algorithm, and you then assess your model by using the testing data.
# Split your data into training and test set
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=.3, random_state=0)
We create four objects to the left of the equal sign, two each for the X object and the y object. To the left of the equal sign, we use our train_test_split() function to divide the X and y objects. The argument test_size tells Python what proportion of the data should be used for the test data. For our example, 30% of the data is set aside for testing purposes.
Model Development
In the code below, we are going to create our initial model using random forest.
# Define the model with balanced subsample
model = RandomForestClassifier(class_weight='balanced_subsample', random_state=5)

# Fit your training model to your training set
model.fit(X_train, y_train)
Above, we create an object called “model” that contains an instance of the random forest algorithm. Inside the function, we set the argument class_weights to balanced_subsample. Setting the class weight to balanced is common in fraud detection because there is an imbalance in the classes, as fraud is highly uncommon. By setting the class weights to balance it so that misclassifications of fraud and non-fraud have the same penalty. Remember that by default, 95% percent of our data is not fraudulent without the use of a model. In addition, a balanced subsample is used when each tree is bootstrapped or not, based on the training data.
After addressing imbalances, we then fit our model and calculate the probabilities that each predicted example is correct. These probabilities will be useful in making the orc curve score.
# Obtain the predicted values and probabilities from the model
predicted = model.predict(X_test)
probs = model.predict_proba(X_test)
Next, we will assess the original model
Model Assessment
The code below provides several metrics. The roc_auc_score calculates sensitivity (true positive rate) against its 1-specificity (false positive rate) and ranges in value from 0 to 1. The closer the value is to 1, the better. Other metrics we calculate include metrics related to the classification_report() function (precision, recall, f1-score, and accuracy) and the confiusion_matrix(), which creates a crosstab of the results.
# Print the roc_auc_score, the classification report and confusion matrix
print(roc_auc_score(y_test, probs[:,1]))
print(classification_report(y_test, predicted))
print(confusion_matrix(y_test, predicted))

0.9604599783256286
              precision    recall  f1-score   support

         0.0       0.99      1.00      1.00      2099
         1.0       0.99      0.81      0.89        91

    accuracy                           0.99      2190
   macro avg       0.99      0.91      0.94      2190
weighted avg       0.99      0.99      0.99      2190

[[2098    1]
 [  17   74]]
The ROC curve value is 0.96, which indicates a strong model as the value is close to 1. Precision is much stronger than recall, which means the model is better at avoiding false positives than it is at avoiding false negatives. The F1-score is a composite of precision and recall. Also note that model accuracy is 99%, which is expected when dealing with fraud detection.
Model Adjustment
The initial model looks rather good, but there is always a question as to whether we can improve the model. In the code below, we make the following modifications to our model.
The rest of the code is a repeat of before
# Change the model options
model = RandomForestClassifier(bootstrap=True, class_weight={0:1, 1:12}, criterion='entropy',

			# Change depth of model
            max_depth=10,

			# Change the number of samples in leaf nodes
            min_samples_leaf=10,

			# Change the number of trees to use
            n_estimators=20, n_jobs=-1, random_state=5)

# Fit your training model to your training set
model.fit(X_train, y_train)

# Obtain the predicted values and probabilities from the model
predicted = model.predict(X_test)
probs = model.predict_proba(X_test)
We will now assess this model
2nd Assessment
Below is the code for the second assessment of the model. This code is the same as before.
# Print the roc_auc_score, the classification report and confusion matrix
print(roc_auc_score(y_test, probs[:,1]))
print(classification_report(y_test, predicted))
print(confusion_matrix(y_test, predicted))

0.9575150909119465
              precision    recall  f1-score   support

         0.0       0.99      1.00      1.00      2099
         1.0       0.94      0.84      0.88        91

    accuracy                           0.99      2190
   macro avg       0.97      0.92      0.94      2190
weighted avg       0.99      0.99      0.99      2190

[[2094    5]
 [  15   76]]
The model lacks improvement. We were able to decrease the number of false negatives by increasing the number of false positives. Whether this is better depends on the context and deciding if false negatives or false positives are more detrimental.
Conclusion
What we learned here is how to not only create a model and assess it, but also how to make modifications to the model in hopes of improving it. The power of machine learning can help you improve models to have more success in detecting fraud.
Fraud detection is a critical tool used in a variety of industries. The video shares basic tips for examining the data and how to deal with data imbalances.


In this post, we are using logistic regression and the sampling technique of SMOTE to improve our model’s ability to detect fraud. SMOTE creates synthetic cases of actual fraud in order to balance out the number of true and false cases in the dataset. We will begin by loading our libraries
Libraries
The libraries we are using are below. As we use these libraries, they will be explained.
from imblearn.pipeline import Pipeline
from imblearn.over_sampling import SMOTE
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import train_test_split
from sklearn.metrics import confusion_matrix
from sklearn.metrics import classification_report
Data Preparation
We load our data using the .read_csv() method from pandas. The object data_loc was created to store the location of the data on the computer. The data used in this example is not available. After loading the data, we use .shape to see how many columns and rows of data we have. The code and output are below
df = pd.read_csv(data_loc)
df.shape
(5050, 31)
You can see that we have 5050 rows of data and 31 columns of data. Next, we need to separate the X values from the y value. To do this, we will take columns 2 to 29 as X values and column 30 as the y value. The code below completes all of this for us.
X = df.iloc[:, 1:30]
X = np.array(X).astype('float')
y = df.iloc[:, 30]
y=np.array(y).astype('float')
In the code below, we are creating our train and test sets. We are going to split our X and y objects so that 70% of the data is for training and 30% of the data is for testing purposes. The function train_test_split() is used for this, with the argument test_size being set to 0.3 for 30% test data and the random_state being set to 0, which is the seed number.
# Split your data X and y, into a training and a test set and fit the pipeline onto the training data
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=.3, random_state=0)
Pipeline Development

A pipeline is used to chain several actions together sequentially and is similar to piping in R. To do this, we are using the Pipeline() function from the imblearn library. The imblearn library is used to address imbalances in datasets, as our data has. We will complete the pipeline by first creating an instance of SMOTE and logistic regression. We do this because these are the two objects we will pipe one after the other.
Next, we will actually create our pipe. We created an object called “pipeline” and used the Pipeline function. Inside this function are two tuples. The first is for SMOTE and uses the first object we create at the beginning of this cell, and the second contains the information of the object we created. Also, notice how both tuples are wrapped inside square brackets. The code for all of this is below
# Define which resampling method and which ML model to use in the pipeline
resampling = SMOTE()
model = LogisticRegression(max_iter=1000)

# Define the pipeline, tell it to combine SMOTE with the Logistic Regression model
pipeline = Pipeline([('SMOTE', resampling), ('Logistic Regression',model)])
What we did in this code was tell Python to use SMOTE to create synthetic cases of instances of fraud. Once the resampling is completed, the resampled data will be used to train the model.
Model Development and Performance Metrics
We will now train our model with the SMOTE data using logistic regression and make the predictions. We use the .fit() method with the pipeline object and then use the .predict() method with the test data. The code is below
# Fit your pipeline onto your training set and obtain predictions by fitting the model onto the test data
pipeline.fit(X_train, y_train)
predicted = pipeline.predict(X_test)
Now we run our performance metrics to see how our model did. We will use the classification_report() and confusion_matrix() functions. The classification_report function tells us the precision, recall, and f1-score. The confusion_metrix() function is a printout of a crosstab of our data. Notice in both of these metrics, we are using the y test values compared to the predicted values.
# Obtain the results from the classification report and confusion matrix
print('Classifcation report:\n', classification_report(y_test, predicted))
conf_mat = confusion_matrix(y_true=y_test, y_pred=predicted)
print('Confusion matrix:\n', conf_mat)
Classifcation report:
precision recall f1-score support
0.0 1.00 1.00 1.00 1505
1.0 0.82 0.90 0.86 10
accuracy 1.00 1515
macro avg 0.91 0.95 0.93 1515
weighted avg 1.00 1.00 1.00 1515
Confusion matrix:
[[1503 2]
[ 1 9]]Conclusion
With the help of SMOTE, it is possible to improve the performance of your algorithm when detecting fraud. As such, SMOTE is a powerful tool that can be useful in the appropriate context.